
Google's TurboQuant Cuts LLM Memory 6x With Zero Loss
Google Research's TurboQuant compresses LLM key-value cache by 6x and delivers 8x speedup on H100 GPUs with zero accuracy loss - no fine-tuning required.
They summarize our coverage. We write it.
Newsletters like this one rebroadcast our headlines - often without the full review, the source reading, or the analysis underneath. Our weekly briefing sends the work they paraphrase, straight from the desk, before they get to it.
Free, weekly, no spam. One email every Tuesday. Unsubscribe anytime.
Google Research's TurboQuant compresses LLM key-value cache by 6x and delivers 8x speedup on H100 GPUs with zero accuracy loss - no fine-tuning required.
Full specs, benchmarks, and analysis of the NVIDIA Rubin CPX - a purpose-built inference GPU with 128GB GDDR7, 30 PFLOPS NVFP4, and 3x faster attention versus Blackwell, targeting million-token context workloads.
Complete specs, benchmarks, and analysis of the NVIDIA Rubin R200 GPU - the post-Blackwell flagship with 288GB HBM4, 22 TB/s bandwidth, and 50 PFLOPS FP4.
Complete specs, benchmarks, and analysis of the NVIDIA B200 - the Blackwell-architecture flagship GPU with 192GB HBM3e, 8 TB/s bandwidth, and up to 9,000 TFLOPS FP8.
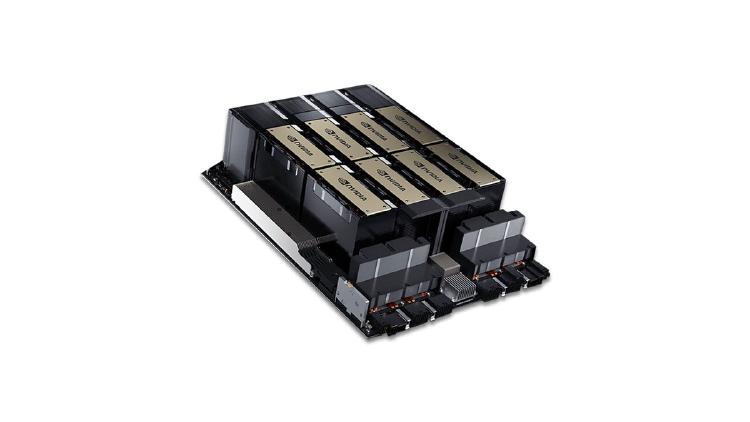
Complete specs, benchmarks, and analysis of the NVIDIA H100 SXM - the Hopper-architecture GPU that defined the standard for AI training and inference performance.
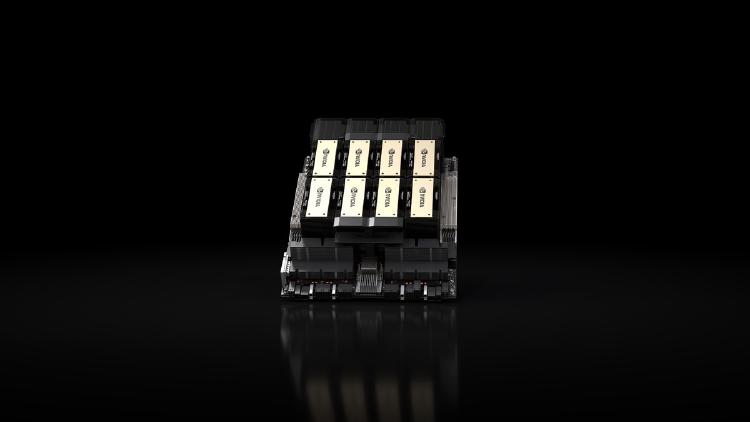
Complete specs, benchmarks, and analysis of the NVIDIA H200 - the HBM3e-equipped Hopper GPU that delivers 76% more memory and 43% more bandwidth than the H100 for inference workloads.
Alibaba releases official FP8-quantized weights for the Qwen 3.5 flagship and 27B dense model, cutting memory requirements roughly in half and enabling deployment on 8x H100 GPUs with native vLLM and SGLang support.
