
Bonsai 1.7B
PrismML's smallest Bonsai checkpoint compresses Qwen3-1.7B under 0.5GB, and now powers the vision-language model behind Qualcomm's Snapdragon AR1 smart glasses demo.
They summarize our coverage. We write it.
Newsletters like this one rebroadcast our headlines - often without the full review, the source reading, or the analysis underneath. Our weekly briefing sends the work they paraphrase, straight from the desk, before they get to it.
Free, weekly, no spam. One email every Tuesday. Unsubscribe anytime.
PrismML's smallest Bonsai checkpoint compresses Qwen3-1.7B under 0.5GB, and now powers the vision-language model behind Qualcomm's Snapdragon AR1 smart glasses demo.
PrismML and Qualcomm demoed a 2-billion-parameter vision-language model running in 1-bit precision on Snapdragon AR1 Gen 1 smart glasses hardware at Snapdragon Summit.
VIDRAFT quantizes its Darwin-36B-Opus MoE model into a 35B GGUF that runs on stock llama.cpp with no GPU, trading GPQA Diamond score for CPU and phone portability.
PrismML compressed a 27B-parameter Qwen model from 54GB to under 4GB using 1-bit and ternary weights, and Apple is evaluating the technology for on-device Siri.
Bonsai 27B compresses Alibaba's Qwen3.6-27B into 1-bit and ternary weights, shrinking a 54GB model to as little as 3.9GB so it runs on an iPhone.
Three new arXiv papers reveal hidden costs in quantized reasoning models, single-token failure triggers, and a new framework that cuts agent memory errors by up to 79%.
Google DeepMind's new QAT checkpoints shrink the Gemma 4 E2B model to under 1GB, making serious on-device AI viable for phones and budget laptops.
Top open-weight models for self-hosting in 2026, with verified VRAM requirements, benchmark data, and tools to deploy them on consumer and server hardware.
The definitive guide to open-weights AI models in 2026 - top picks by size tier, use case, benchmark scores, and deployment hardware. From 400B+ MoE giants to 1B edge models.
How much quality do LLMs lose when quantized from BF16 to INT8, Q6, Q5, Q4, Q3, Q2? Per-model delta tables across MMLU, HumanEval, and perplexity, with VRAM and throughput data for every major quantization format.
A benchmark-driven comparison of the top open-source LLM inference servers - vLLM, SGLang, TGI, llama.cpp, TensorRT-LLM, LMDeploy, and more.
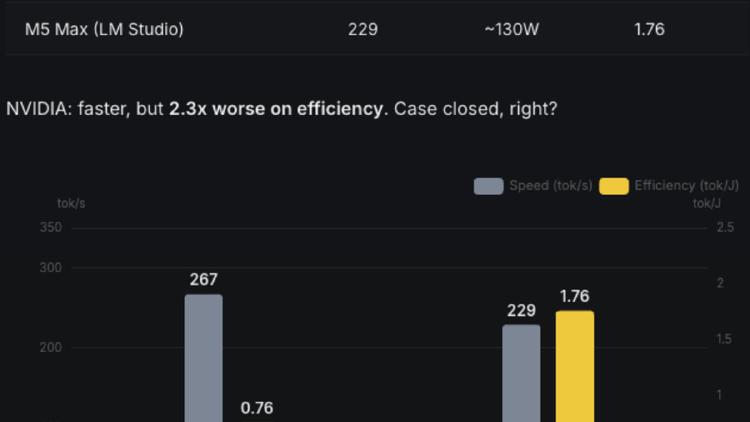
Two researchers fused all 24 layers of Qwen 3.5-0.8B into a single CUDA kernel launch, making a five-year-old RTX 3090 deliver 1.8x the throughput of an M5 Max at equal or better efficiency. The gap was software, not silicon.
