
Best Open-Source LLM Inference Servers 2026
A benchmark-driven comparison of the top open-source LLM inference servers - vLLM, SGLang, TGI, llama.cpp, TensorRT-LLM, LMDeploy, and more.
They summarize our coverage. We write it.
Newsletters like this one rebroadcast our headlines - often without the full review, the source reading, or the analysis underneath. Our weekly briefing sends the work they paraphrase, straight from the desk, before they get to it.
Free, weekly, no spam. One email every Tuesday. Unsubscribe anytime.
A benchmark-driven comparison of the top open-source LLM inference servers - vLLM, SGLang, TGI, llama.cpp, TensorRT-LLM, LMDeploy, and more.
Arcee Trinity-Large-Thinking is a 400B sparse MoE open-source reasoning model that ranks #2 on PinchBench at $0.85/M output tokens, 28x cheaper than Claude Opus 4.6.
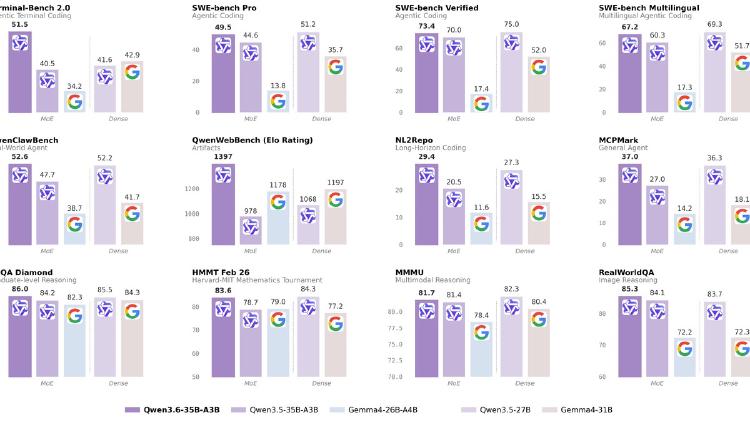
Alibaba's 35B sparse MoE with 3B active parameters delivers 73.4% SWE-bench Verified, multimodal vision and video, 256K context, and DeltaNet hybrid architecture under Apache 2.0.
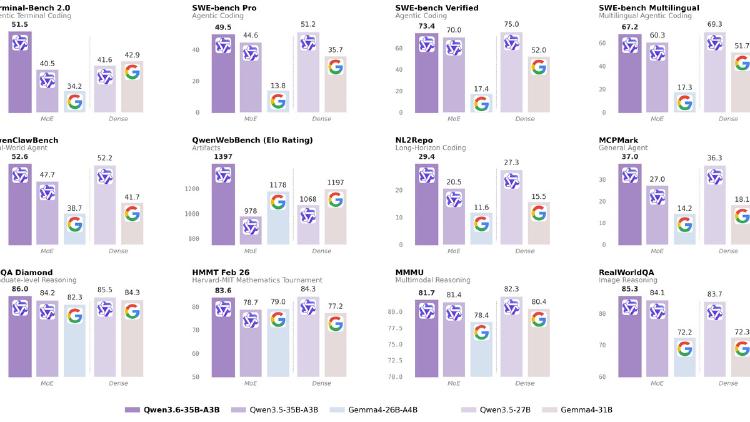
Alibaba's Qwen 3.6-35B-A3B activates only 3B of its 35B parameters per token, scores 73.4% on SWE-bench Verified, handles video and images, and ships under Apache 2.0.
The Caveman plugin for Claude Code cuts 65-87% of output tokens by stripping filler words and using terse fragment-based language. Its new Classical Chinese mode pushes compression even further.
Cal.com moved its core codebase to a private repo after five years of open source, arguing AI tools make public code 5-10x easier to exploit. The community isn't buying it.
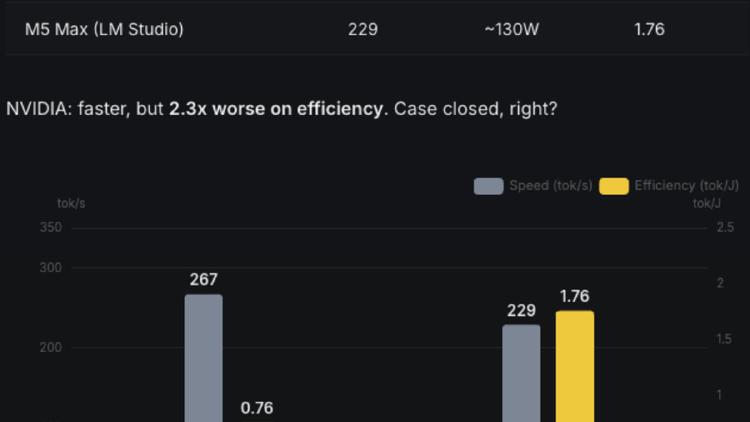
Two researchers fused all 24 layers of Qwen 3.5-0.8B into a single CUDA kernel launch, making a five-year-old RTX 3090 deliver 1.8x the throughput of an M5 Max at equal or better efficiency. The gap was software, not silicon.
A hands-on comparison of the top AI unit test generation tools in 2026, covering Qodo Gen, GitHub Copilot, Diffblue Cover, Keploy, and Tusk.
HappyHorse-1.0 topped the Artificial Analysis Video Arena with a 52-Elo gap over Seedance 2.0 - but the 'open source' model has no public weights, no inference code, and no API.
UC Santa Barbara researchers found 9 of 428 third-party LLM routers actively injecting malicious tool calls, draining crypto, and stealing AWS credentials from AI agent sessions.
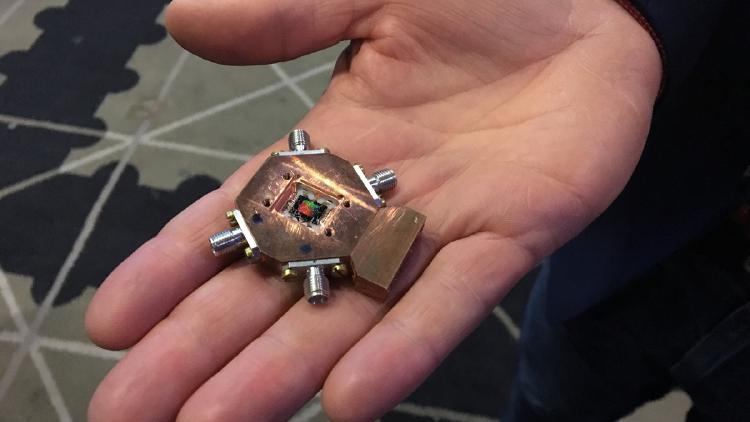
NVIDIA releases two open-source AI models for quantum hardware - a 35B vision-language model that cuts calibration time from days to hours, and CNN decoders that outpace the standard by 2.5x.
Linux 7.0 ships an official AI code policy: disclose AI tool usage with an Assisted-by tag, keep humans on the hook for every line, and stop submitting slop.
