
Open Agent Leaderboard: Model Beats Architecture
IBM Research tests 25 agent configurations across 6 real-world benchmarks and finds backbone model choice matters 58x more than agent framework design.
They summarize our coverage. We write it.
Newsletters like this one rebroadcast our headlines - often without the full review, the source reading, or the analysis underneath. Our weekly briefing sends the work they paraphrase, straight from the desk, before they get to it.
Free, weekly, no spam. One email every Tuesday. Unsubscribe anytime.
IBM Research tests 25 agent configurations across 6 real-world benchmarks and finds backbone model choice matters 58x more than agent framework design.
Raindrop's MIT-licensed Workshop streams every token and tool call from your AI agent to a local browser dashboard, then lets Claude Code write and fix evaluations automatically.
Mira Murati's startup unveils TML-Interaction-Small, a 276B MoE model that hits 0.40-second response latency by listening and generating speech at the same time.
IBM's Granite Embedding Multilingual R2 ships with a 64x context window jump, ModernBERT architecture, and Apache 2.0 licensing that makes it enterprise-safe out of the box.
SU-01 is a 30B-A3B MoE reasoning model from Shanghai AI Lab that achieves gold-medal performance on IMO 2025, USAMO 2026, and IPhO 2024/2025 using a three-stage training recipe and test-time scaling.
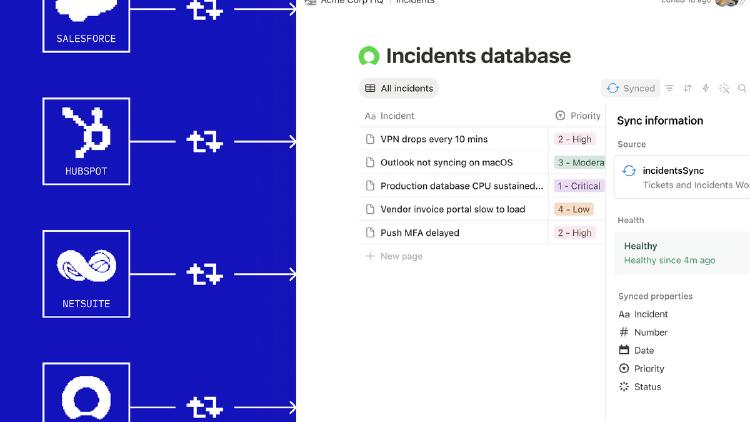
Notion 3.5's Developer Platform adds Workers, live database sync, and first-class Claude Code and Cursor support - turning the workspace into an AI agent orchestration layer.
HiDream-O1-Image is an 8B open-source text-to-image model with a pixel-space diffusion architecture that outperforms 32B FLUX.2 [dev] across five major benchmarks.
NVIDIA Ising is the first open AI model family for quantum computing - a 35B VLM for processor calibration and CNN decoders for real-time error correction, already deployed at 20+ research institutions.
AI2's federally backed OMAI compute cluster is now running on NVIDIA Blackwell Ultra hardware and has already shipped OLMo, Molmo 2, and MolmoAct models fully open to researchers.
Zyphra's ZAYA1-8B matches Claude 4.5 Sonnet on HMMT 2025 math benchmarks at just 760M active parameters, trained entirely on AMD Instinct MI300X GPUs under Apache 2.0.
Zyphra's ZAYA1-8B is an 8.4B-parameter MoE reasoning model with only 760M active parameters that matches DeepSeek-R1-0528 on math and coding benchmarks while running at a fraction of the compute cost.
MiniMax M2.7 is the first open-weight frontier model to automate 30-50% of its own training pipeline - but a controversial license change and sluggish speed complicate the story.
