Articles Tagged "Multimodal"

Kimi K2.5

Kimi K2.5

Moonshot AI's Kimi K2.5 is a 1T-parameter MoE model activating 32B per token with native multimodal vision via MoonViT-3D, Agent Swarm coordination of up to 100 sub-agents via PARL, and top-tier math and coding benchmarks under a modified MIT license.
Gemini 2.5 Flash-Lite

Gemini 2.5 Flash-Lite

Google's cheapest Gemini model pairs a 1M-token context window with $0.10/$0.40 per million token pricing, multimodal input, and 359 tokens/second throughput for high-volume production workloads.

Google Gemma 3 27B

Google Gemma 3 27B

Google Gemma 3 27B is a 27B dense multimodal model supporting text and vision with a 128K context window, 140+ languages, and single-GPU deployment - the most capable open model at its size class.

GPT-4o mini

GPT-4o mini

OpenAI's budget API workhorse pairs 128K context with $0.15/$0.60 per million token pricing, solid coding benchmarks, and the broadest third-party ecosystem of any small model.

Llama 4 Maverick

Llama 4 Maverick

Meta's Llama 4 Maverick packs 400B total parameters into a 128-expert MoE architecture with only 17B active per token, beating GPT-4o on Chatbot Arena while matching DeepSeek V3 on reasoning at half the active parameters.

Llama 4 Scout

Llama 4 Scout

Meta's Llama 4 Scout is a 109B-total, 17B-active MoE model with 16 experts and a 10M-token context window - the longest of any open-weight model - with native multimodal support for text and images.

Mistral Large 3

Mistral Large 3

Mistral Large 3 is a 675B-parameter MoE model activating 41B per token with native multimodal support, a 256K context window, and Apache 2.0 licensing - Europe's first frontier-class open-weight model.

Mistral Small 3.2

Mistral Small 3.2

Mistral Small 3.2 is a 24B dense model with strong function calling, multimodal vision, and 128K context under Apache 2.0 - optimized for production tool-use pipelines and EU-compliant deployments.

Qwen3.5-122B-A10B

Qwen3.5-122B-A10B

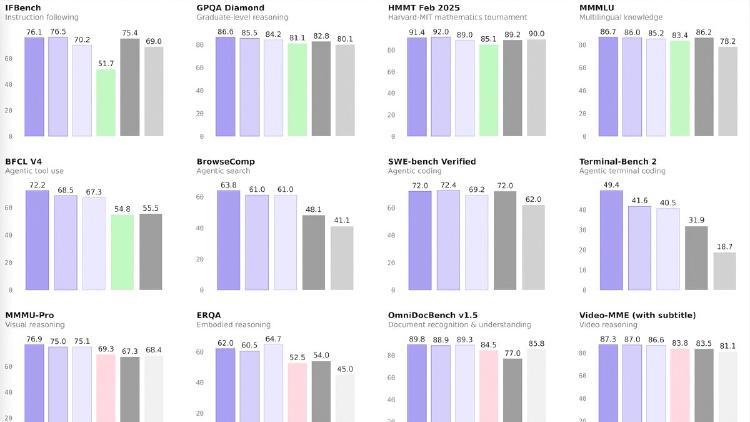
Qwen3.5-122B-A10B is a 122B-parameter MoE model activating 10B parameters per token, narrowing the gap between medium and frontier models with top scores in GPQA Diamond (86.6), MMMU (83.9), and OCRBench (92.1). Apache 2.0 licensed.