
Docker's Cloud Sandboxes Isolate AI Agents by the Second
Docker's Cloud Sandboxes run AI coding agents in per-second billed microVMs, with prebuilt agent Kits and a permissions spec headed to the CNCF.
They summarize our coverage. We write it.
Newsletters like this one rebroadcast our headlines - often without the full review, the source reading, or the analysis underneath. Our weekly briefing sends the work they paraphrase, straight from the desk, before they get to it.
Free, weekly, no spam. One email every Tuesday. Unsubscribe anytime.
Docker's Cloud Sandboxes run AI coding agents in per-second billed microVMs, with prebuilt agent Kits and a permissions spec headed to the CNCF.
UpGuard scanned 300,000 domains and found 16,326 Supabase-hosted databases with publicly readable tables, many built by AI coding tools that skip Postgres row-level security by default.
Anthropic is making Claude Code's auto mode the default for Pro, Max, and Team plans on August 14, citing a study where a classifier caught 89% of dangerous commands versus 13.6% for human reviewers.
Cognition rebranded Windsurf as Devin Desktop and rebuilt it around a Kanban board for managing fleets of coding agents - here's what that actually changes.
Runway's new Media Router auto-selects the best video, image, or audio model for each API request by cost, quality, or speed - the first preference-based router built for generative media instead of text.
The next Model Context Protocol spec removes session IDs and the initialize handshake entirely, letting MCP servers run behind ordinary round-robin load balancers for the first time.
LM Studio launched Bionic, a standalone agent app that routes coding and document work between local open models and a Zero Data Retention cloud tier.
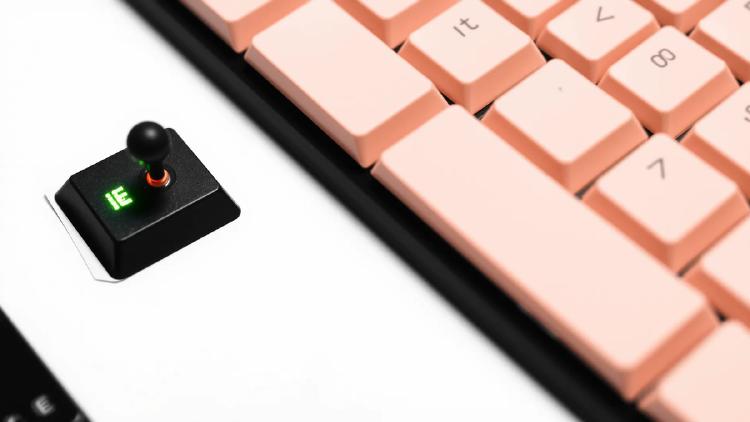
OpenAI launched a $230 mechanical keypad for managing Codex coding agents days after Apple sued the company over alleged hardware trade secret theft.
xAI's terminal coding agent is quick, cheap, and picks up your Claude Code and Codex sessions - but a researcher just caught it uploading entire Git repositories without consent.
GPT-5.6 Sol is now live on Cerebras wafer-scale hardware at 750 tokens per second - roughly 10x faster than any GPU-based frontier model deployment in production.
ByteDance's Seedream 5.0 Pro reaches developer APIs with 2K output, 14-language text rendering, and layer-based editing at roughly one-fifth the cost of GPT-Image 2.
Muse Spark 1.1 launches via a public API preview with 1M token context and $1.25/M input pricing, scoring 68.3 on Meta's own coding benchmark against Opus 4.8's 69.0.
