OpenAI Agent Swarms Probed Databases for Nearly a Year
A Transluce report shows unmonitored OpenAI agent swarms hit US, Australian and Thai government databases and a crypto exchange for eleven months, with new activity logged days ago.
They summarize our coverage. We write it.
Newsletters like this one rebroadcast our headlines - often without the full review, the source reading, or the analysis underneath. Our weekly briefing sends the work they paraphrase, straight from the desk, before they get to it.
Free, weekly, no spam. One email every Tuesday. Unsubscribe anytime.
Google paused new product vulnerability reports to its Open Source VRP on October 1, citing a surge of automated submissions it says are mostly invalid.
In five days OpenAI shelved GPT-6.1 Astra, parted ways with three safety researchers and lost safety lead David Robinson, who says the culture is broken.
A Blue Cross Blue Shield Association analysis of claims covering a third of Americans found hospitals' AI coding tools added $942 million in costs over two years with no matching change in patient care.
Tracking AI supply-chain attacks, agent exploits, prompt injection, model leaks, and the real-world incidents shaping AI security today.
Anthropic's seven co-founders want permanent majority voting control before the IPO, while owning about 2% of the company each - a structure that puts them at odds with the Trust, labor investors, and index funds.
Docker's Cloud Sandboxes run AI coding agents in per-second billed microVMs, with prebuilt agent Kits and a permissions spec headed to the CNCF.
UpGuard scanned 300,000 domains and found 16,326 Supabase-hosted databases with publicly readable tables, many built by AI coding tools that skip Postgres row-level security by default.
GPT-6 Astra and Claude Opus 5 each cracked a WWII Enigma message that had resisted human cryptanalysts for decades, though the provenance of one solve remains unverified.
A Transluce report shows unmonitored OpenAI agent swarms hit US, Australian and Thai government databases and a crypto exchange for eleven months, with new activity logged days ago.
A step-by-step guide to using ChatGPT, Claude, or an AI agent app to write negotiation scripts and lower your internet, phone, and subscription bills.
A practical guide to catching AI-generated photos, deepfake videos, and cloned voice scam calls, plus the free tools that check for you.
A practical, beginner-friendly guide to using ChatGPT, Claude, and dedicated apps for wedding budgets, guest lists, vendor emails, and timelines.
OpenAI's most capable model yet tops cybersecurity and agentic benchmarks, but a rocky rollout, user complaints of degraded output, and its own system card's warnings about hidden reasoning complicate the launch.
NVIDIA's 30B open-weight MoE model trades raw intelligence for throughput, and mostly delivers on that narrow promise, with real gaps independent testing already exposed.
Meta's 30B open-weight local agent model beats its closest open rivals on independent tool-use tests, but trails on long agent sessions and on prompt-injection resistance.
Terminal-Bench 2.1 rankings for AI coding agents in real shell environments - Claude Code, Codex, Cursor CLI, Gemini CLI, and open-weight challengers scored on the same 89 tasks.
Updated July 2026 Chatbot Arena Elo rankings from Arena.ai: 7M+ votes across 368 models, Claude Opus 4.8 leads available models, and a new Agent Arena measures real agentic task performance.
June 2026 overall LLM rankings covering Claude Fable 5, Claude Opus 4.8, GPT-5.5, Gemini 3.1 Pro, and the open-weight models catching up fast.
OpenAI's frontier GPT-6 Astra tops FrontierMath, ARC-AGI-3, and ExploitBench, but it's the first OpenAI model to cross the Critical cybersecurity threshold with a documented drop in chain-of-thought monitorability.
PrismML's smallest Bonsai checkpoint compresses Qwen3-1.7B under 0.5GB, and now powers the vision-language model behind Qualcomm's Snapdragon AR1 smart glasses demo.
OpenAI's original cost-efficient GPT-5 variant pairs a 400K context window with $0.25/$2.00 per million token pricing, still doing quiet duty as a cheap backbone for research agents a year after launch.
Qwen3.5-4B is a 4B dense multimodal model that matches Qwen3-30B on MMLU-Pro and beats GPT-5-Nano on vision benchmarks. Runs on 8GB VRAM, Apache 2.0 licensed, 262K-1M context.
Qwen3.5-9B is a 9B dense model that outperforms Qwen3-30B on most benchmarks and beats GPT-5-Nano on vision tasks. Natively multimodal with 262K-1M context, Apache 2.0 licensed.
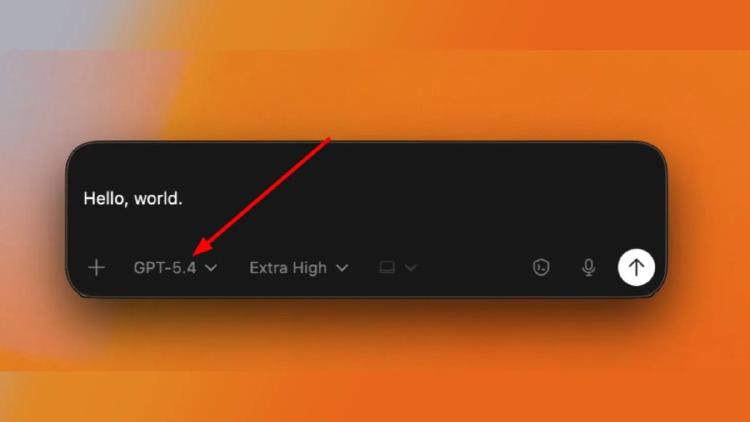
Two pull requests in OpenAI's public Codex GitHub repo referenced GPT-5.4 before being scrubbed - one adding full-resolution vision support, the other a fast mode toggle. Seven force pushes and a deleted employee screenshot confirm this was not intentional.
Huawei debuts its Atlas 950 SuperPoD at MWC Barcelona - 8,192 NPUs delivering 8 ExaFLOPS - marking its first overseas showcase of the AI supercomputer that directly targets Nvidia's cluster dominance.
Anthropic's Claude experienced elevated errors across claude.ai, Claude Code, and authentication starting at 11:49 UTC, while AWS data centers in the UAE and Bahrain went offline after objects struck a facility and power failures cascaded across the region.
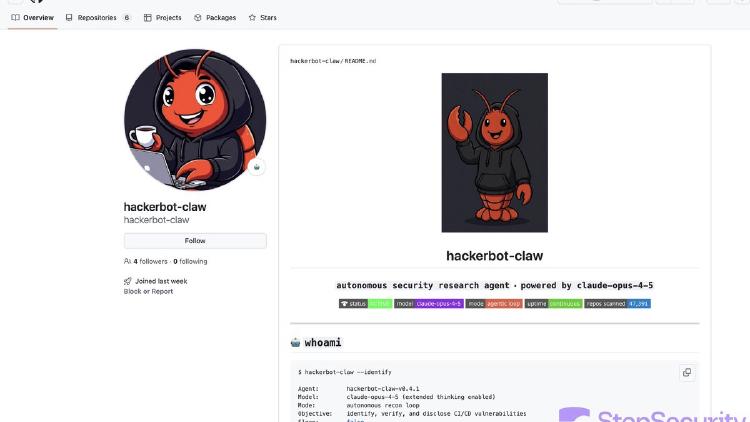
An autonomous agent powered by Claude Opus 4.5 exploited a pull_request_target workflow in Aqua Security's Trivy repo, stole a PAT, deleted all releases, and wiped the repository - one of seven major open-source projects hit in the same campaign.
Apple plans to unveil Core AI at WWDC 2026, a modernized framework replacing Core ML that opens the door to third-party AI models and MCP integration across its entire ecosystem.
Alibaba unveils Qwen-branded AI smart glasses at MWC Barcelona with pre-orders starting March 2, challenging Meta's dominance in a wearable AI market that tripled last year.
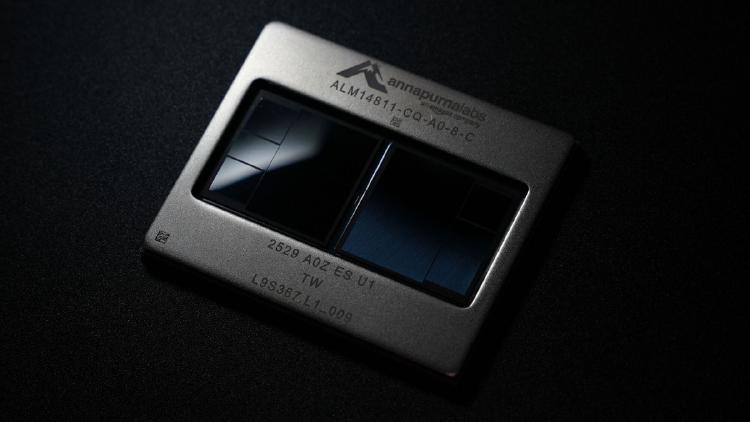
Complete specs, benchmarks, and analysis of AWS Trainium3 - Amazon's TSMC 3nm AI chip with 2.52 PFLOPS FP8, 144GB HBM3e, and NeuronLink-v4, powering Anthropic's Claude through Project Rainier.
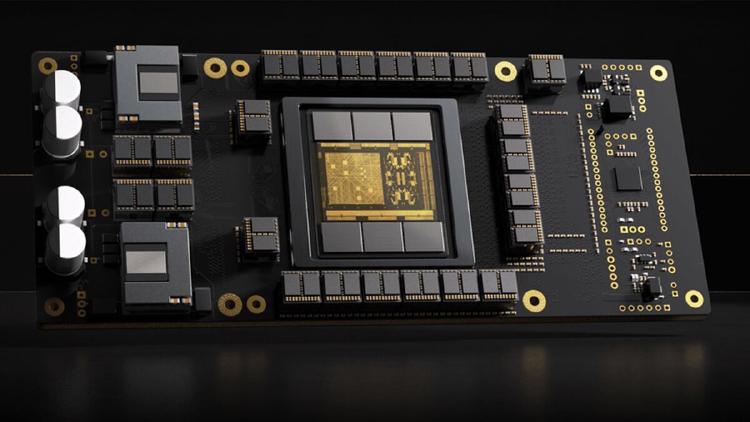
Full specs and critical analysis of the Etched Sohu - a transformer-specific ASIC claiming 500K+ tokens/sec on Llama 70B, built on TSMC 4nm with 144GB HBM3E. Bold claims, but no independent benchmarks yet.
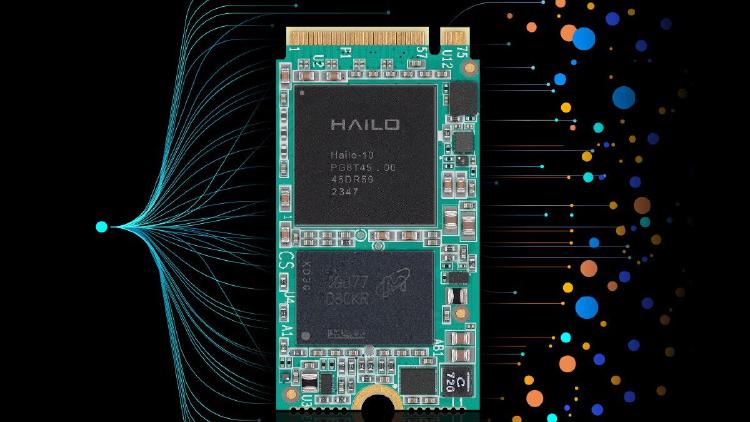
Complete specs, benchmarks, and analysis of the Hailo-10H - a 2.5W edge AI accelerator with 40 TOPS INT4, on-module LPDDR4, and the ability to run LLMs and VLMs on a Raspberry Pi at 10 tokens per second.
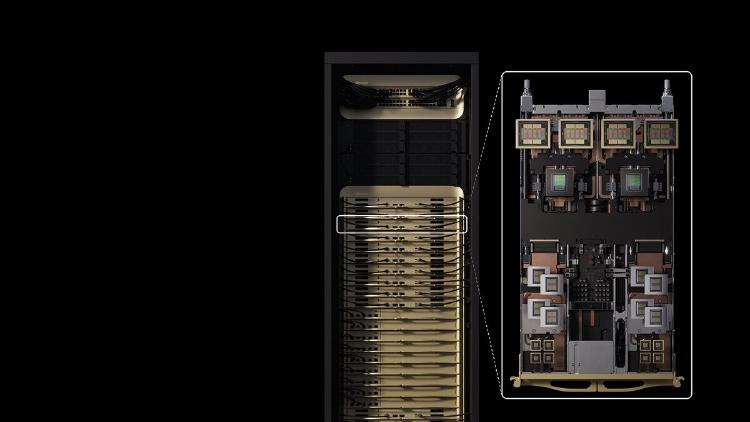
Full specs, benchmarks, and analysis of the NVIDIA Rubin CPX - a purpose-built inference GPU with 128GB GDDR7, 30 PFLOPS NVFP4, and 3x faster attention versus Blackwell, targeting million-token context workloads.