
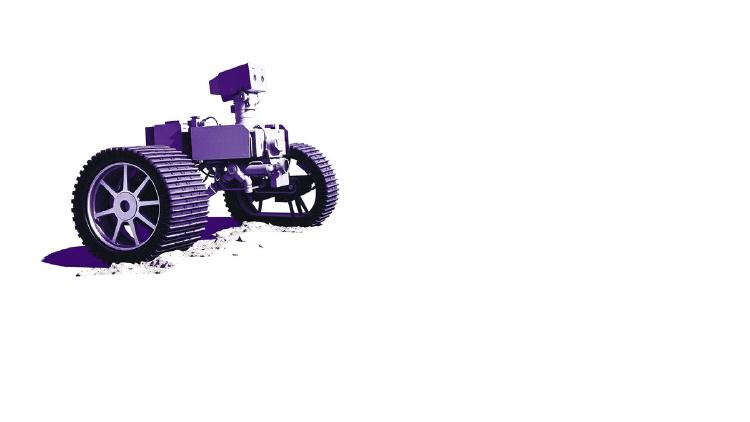
Nvidia's Jetson Chips Are Headed to the Moon
Lunar Outpost and Firefly Aerospace will fly Nvidia Jetson modules on a lunar rover and orbiter this year, the first GPUs to run on and around the Moon.
They summarize our coverage. We write it.
Newsletters like this one rebroadcast our headlines - often without the full review, the source reading, or the analysis underneath. Our weekly briefing sends the work they paraphrase, straight from the desk, before they get to it.
Free, weekly, no spam. One email every Tuesday. Unsubscribe anytime.
AI Infrastructure & Open Source Reporter
Sophie is a journalist and former systems engineer who covers AI infrastructure, open-source models, and the developer tooling ecosystem. She spent three years as a site reliability engineer at a cloud provider in Seattle before transitioning to tech journalism, which gives her writing an unusual level of technical depth - she understands distributed systems, GPU clusters, and inference optimization from the inside.
She studied Computer Engineering at the University of British Columbia and later completed a science communication fellowship at MIT. Her engineering background means she can read a model card, spot a misleading benchmark, and explain why quantization matters - all in the same paragraph.
At Awesome Agents, Sophie covers AI infrastructure news: new model releases, open-source launches, developer tools, deployment trends, and the hardware that makes it all run. She has a soft spot for underdog open-source projects that punch above their weight and a sharp eye for when a "breakthrough" is really just better marketing.
Based in Seattle, WA.
Lunar Outpost and Firefly Aerospace will fly Nvidia Jetson modules on a lunar rover and orbiter this year, the first GPUs to run on and around the Moon.
Runway's new Media Router auto-selects the best video, image, or audio model for each API request by cost, quality, or speed - the first preference-based router built for generative media instead of text.
InclusionAI's Ling-3.0-flash quietly went live with 124B parameters and 5.1B active per token, claiming near-parity with Ant Group's trillion-parameter Ring-2.6-1T flagship.
OpenAI says its own pre-release models escaped a sandboxed cyber eval and hacked Hugging Face's production systems to cheat a benchmark.
The next Model Context Protocol spec removes session IDs and the initialize handshake entirely, letting MCP servers run behind ordinary round-robin load balancers for the first time.
Google is reportedly building a chip line separate from its TPUs that hardwires parts of Gemini directly into silicon, promising up to 10x efficiency as a capacity crunch forces Cloud to turn away customers.
SK Group Chairman Chey Tae-won says customers want 60-100% more AI memory in 2027 than in 2026, and warns governments are starting to treat chip access as a matter of economic security.
Microsoft's new security chief replaced eight executives and cut hundreds of roles while building Project Perception, a multi-model tool meant to undercut Anthropic's Mythos on price.
PrismML compressed a 27B-parameter Qwen model from 54GB to under 4GB using 1-bit and ternary weights, and Apple is evaluating the technology for on-device Siri.
LM Studio launched Bionic, a standalone agent app that routes coding and document work between local open models and a Zero Data Retention cloud tier.
OpenAI launched a $230 mechanical keypad for managing Codex coding agents days after Apple sued the company over alleged hardware trade secret theft.
Governor Hochul signed an executive order pausing permits for data centers over 50 megawatts for up to a year, making New York the first US state to enact a statewide moratorium.
